
We Merged 143 PRs in a Week. That Number Tells You Very Little.
One person and a set of coding agents merged 143 pull requests into Fleet in a single week. Here's what those PRs were made of, why PR and line counts measure effort rather than results, and what we'd measure instead.
In the week of 5 October, 143 pull requests were merged into Fleet’s main branch. All of them came from one person working with coding agents: 569 of the 572 non-merge commits that week name a Claude model as co-author. The median PR went from opened to merged in about 11 minutes, and together they changed 179,421 lines.
That sounds like a lot of work, and it was. But the number mostly tells you how the work was sliced. It says very little about what got better for the people who use Fleet.
Our own first count shows how slippery it is. We took it on Friday evening, without saying so, and the week stood at 93. By Sunday night, Friday alone had reached 50 and the weekend had added 39 more. A count that moves by half depending on when you look is a poor thing to steer by.
What 143 PRs were made of
We sorted every PR from that week by hand, from its title and description. Here’s how it splits:
| Kind | PRs |
|---|---|
| Feature | 55 |
| Refactor | 43 |
| Fix | 16 |
| Flaky-test fixes | 12 |
| Other test and CI changes | 2 |
| Harness work | 8 |
| Docs and plans | 6 |
| Revert | 1 |
The 55 feature PRs add up to about 16 features. Fleet mods took 22 PRs on its own, and multi-machine support took 15 feature PRs, plus 3 refactors. Agent pages took 3, and context-window tracking and release notes took 2 each. The other eleven features were one PR each, such as the phone app, pinned sessions and a guided walkthrough of a change.
26 of the 43 refactors were one restructuring. From #435 to #463, the server code was reorganised one piece per PR: a large SessionOrchestrator class was split up, and a catch-all Services folder was emptied into feature folders. We think shipping that as 26 small steps was right, because each one was easy to review and easy to undo. It also made the week’s PR count look 25 PRs bigger than one large refactor would have.
Lines are no better. The 179,421 lines changed break down like this:
APP CODE
+79,003 / −14,860
The product itself: server, client, mods host, plugins, scripts and CI config.
EVERYTHING ELSE
Tests: +57,982 / −1,495
Mockups, plans and docs: +25,218 / −122, including about 600 lines of skill prompts that ship in the product
Lockfiles and generated files: +741
The biggest single PR that week, the phone app, was 31,322 lines. Of those, 19,339 were app code. The rest were tests, mockups and docs. None of that is bad. Tests and mockups are part of how agents check their own work. But a line count treats a mockup page and a server change as the same thing.
Effort, output, outcome, mission
Kent Beck put names to this in his Prodacity talk, posted in September. He describes a sequence. You put in effort, and you get a new feature you can deliver, which is “output”. Customers use it and their behaviour changes, which is outcome. And outcome leads to “changes in our accomplishment of the mission”.
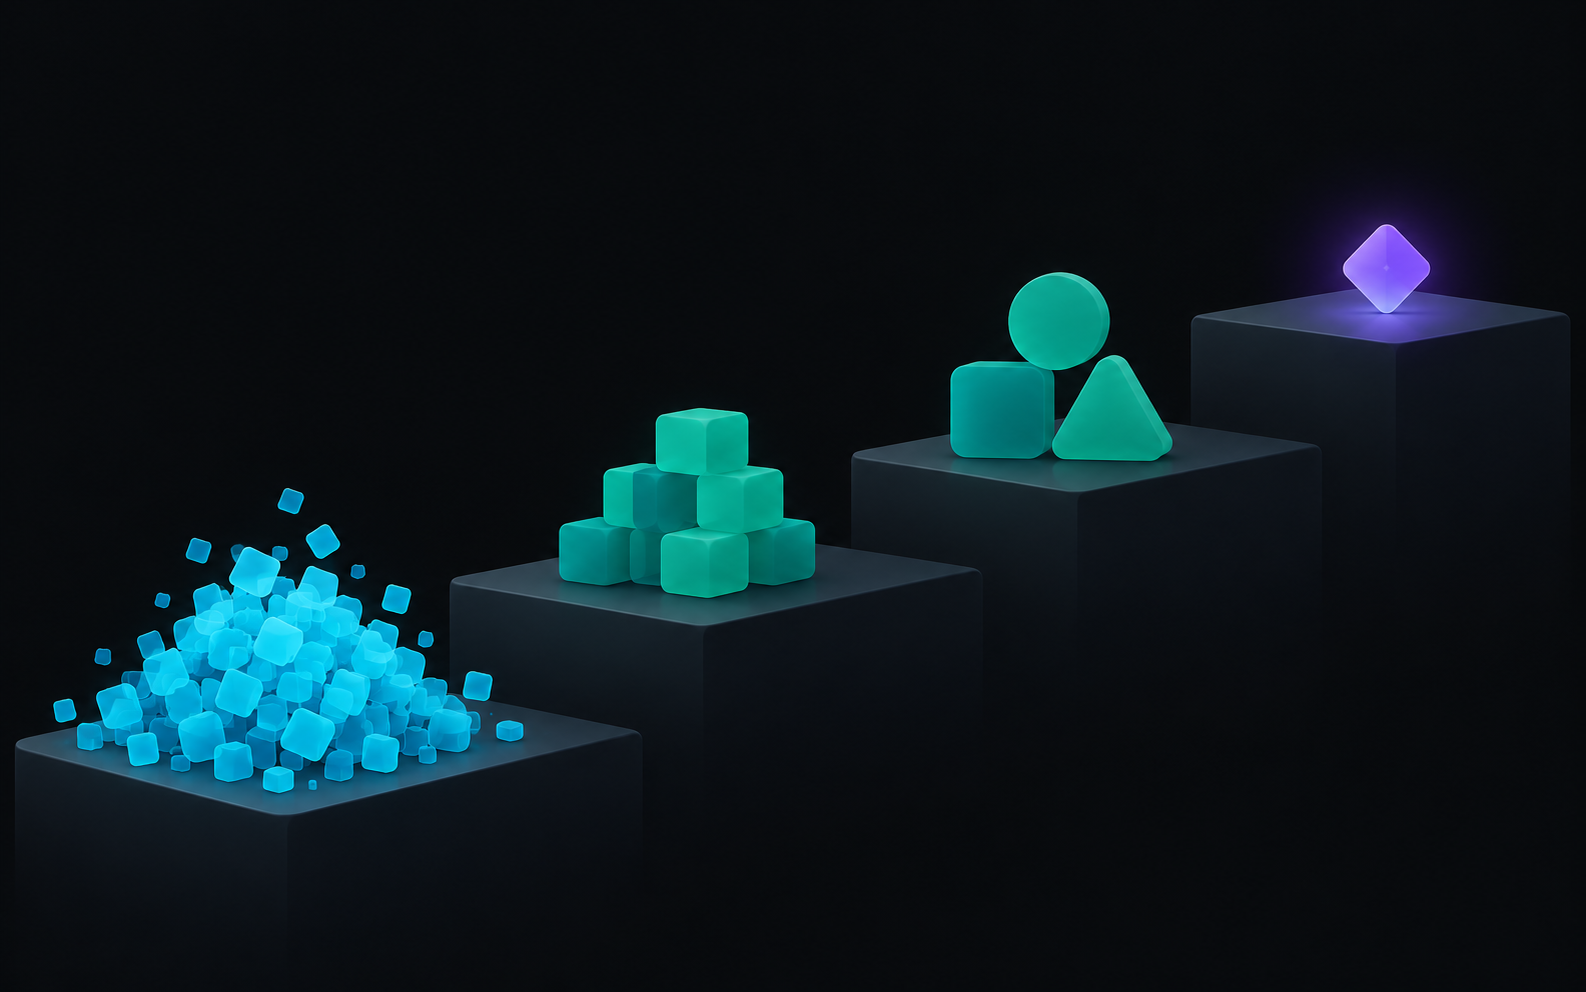
PRs and lines sit at the bottom of that ladder. Beck is blunt about it:
“Whether it’s lines of code, which we’ve known was balderdash for a very, very long time and somehow it’s back, PR count, anything which is a measure of effort or a measure of output is per definition not a measure of mission.” — Kent Beck, 47:10
He has a line for big generated codebases too: “200,000 lines is not 10 times as much as 20,000 lines”. We count them anyway because they’re “the easiest thing to measure. And so we look for our keys under the lamppost.”
The risk goes beyond measuring the wrong thing. Beck calls Goodhart an optimist: once a measure becomes a goal, “people will twist the entire system out of shape. They’ll make it worse in order to get better measures.” The version most people quote, “when a measure becomes a target, it ceases to be a good measure”, comes from a 1997 paper by Marilyn Strathern, who took the name “Goodhart’s law” from the accounting scholar K. Hoskin. It goes back to Charles Goodhart’s 1975 observation about monetary policy. Agents make this worse in a specific way. They can raise a PR count on request at almost no cost: split a change in two and the number goes up.
Everyone is counting
We’re not the only ones with a big number.
Travis Frisinger wrote about HydraFlow v2, 8th Light’s software factory. It started as a specification on 4 September, and “six weeks later, it has merged roughly 1,100 pull requests.” To his credit, the next paragraph says it plainly: “The pull request count is a measure of throughput, not proof of quality.”
Anthropic’s Claude Code team published how they review code when Claude writes most of it. Changes landing per day in Anthropic’s monorepo went from about 2,500 in May to more than 30,000 in September. For Claude Code’s own repository, they pair throughput with something that can go wrong: “merged pull requests to Claude Code’s codebase more than doubled while the share that had to be reverted fell by more than 40 percent.”
“Revert and incident rates are the guardrail: if they rise, we haven’t saved human time, we’ve only moved it.” — How the Claude Code team does code review
That’s the useful move. A throughput number on its own can only go up. Pair it with a number that would get worse if the work were bad, and the two together start to say something.
What we can measure instead
All of these come from the same public GitHub data as the PR count. None of them is a measure of mission. But each one can go wrong, which a PR count can’t.
Reverts. In 550 merged PRs since April, there has been one revert, and it came in that same week. It undid #483 4.8 hours after it merged. Its description gives a design and process reason, not a bug. One revert in 550 looks excellent. It may say as much about habit as quality: in a repo that fixes forward, problems show up as new fixes, not reverts.
Follow-up fixes. 4 of the week’s 143 PRs, or 2.8%, fixed a defect in a PR merged in the previous seven days and named it. Across all 550, it’s 24, or 4.4%. That’s a lower bound, because it only catches fixes that cite a PR number.
Hours main was red. Fleet’s CI runs on every push to main. That week, main was failing for 21.2 hours of wall-clock time, or 12.6% of the week, and 9 PRs merged while it was red. The longest stretch was 15 hours, from Saturday afternoon into Sunday morning (UTC). From 7 September to 18 October, main was red for 42.5 hours in total.
Flaky tests. 12 of the week’s PRs made a test or CI more reliable, by our count. Only 4 say so in the title, with words like “flaky”, “racy” or “deterministic”. Most of the rest are tests that now wait for an event instead of assuming it has happened.
This is close to how DORA measures software delivery: it pairs throughput factors with instability factors, such as “change fail rate” and “deployment rework rate”. The numbers above are a small-team version of that.
A PR count can only go up. Pair it with a number that would get worse if the work were bad.
What none of them tells you is whether Fleet got better for the people using it. Did anyone use the new phone app that week? Did pinned sessions change how people work? GitHub can’t answer that. Beck’s point about mission is that its value is “bursty”: “You don’t see it until a crisis happens and then you realize that you’re ready for the crisis.” It’s hard to measure, and it’s the part that matters.
What we’d do with the number now
If you’re running agents and the PR counts are climbing, this is what we’d suggest:
- Count features, not PRs. Group PRs by what a user would notice. 143 PRs and about 16 features is a more honest sentence than 143 PRs alone.
- Give every count a window and a time. Our 93 and our 143 describe the same week. Say Monday to Sunday, in which time zone, as of when.
- Split lines by kind. App code, tests, mockups and docs, and generated files are different things. Report them separately or not at all.
- Pair throughput with something that can fail. Reverts, follow-up fixes, hours main was red, and PRs merged while red are all cheap to get from data you already have.
- Don’t make any of them a target. The moment a number becomes the goal, agents will be very good at moving it.
- Ask about mission in words. What can people do now that they couldn’t last week? Write it down. If the answer is “nothing yet”, that’s worth knowing too.
The short version
- 143 PRs in a week was about 16 features, one large refactor in 26 steps, and a lot of tests and fixes. The PR count was the least informative number in the set.
- PR and line counts measure effort and output. Beck’s ladder is a useful reminder that outcome and mission sit above them, and are harder to count.
- The useful numbers are the ones that can get worse: reverts, follow-up fixes, and hours main was red. Even those only tell you the work held up. Whether it mattered is a separate question.
Sources
We pulled Fleet’s PR data from the GitHub API at 11:36 UTC on 18 October 2026, with main at e25a179. Weeks run Monday to Sunday in UTC, by merge time, and only PRs merged into main count. We sorted PRs into kinds and features by hand, from titles and descriptions, so those groupings are our judgement. Lines are additions plus deletions as GitHub reports them. “Red” means the CI workflow’s latest completed run on main had failed, ignoring runs cancelled by a newer push. Follow-up fixes are PRs whose title says they fix something and that cite an earlier PR merged within seven days. We read every candidate, and left out the revert because it wasn’t fixing a defect. “Red” hours are wall-clock time from the first failing commit to the next passing run.
Fleet (pgermishuys/weave-fleet)
- Merged PRs: the week of 5 October (143), Monday to Friday (104), 17 April to 17 October (550).
- Single-PR features that week: #374, #376, #377, #379, #386, #387, #392, #399, #400, #410, #434.
- The restructuring: #435 to #463.
- The revert: #485, reverting #483.
- CI: runs of the CI workflow on pushes to main.
Kent Beck
- Kent Beck, “Software Engineering in the Age of AI”, Prodacity 2026, Rise8 on YouTube, 29 September 2026. Quotes at 44:05, 45:20, 45:58, 47:10, 47:45 and 48:33.
Others counting
- Travis Frisinger, “In a Room Full of Builders, Where Are the Architects?”, AiBuddy.software, 14 October 2026.
- Addy Osmani, Morgan Westlee Lunt and Qing Wang, “How the Claude Code team does code review”, claude.dev, 15 October 2026.
- DORA, “DORA’s software delivery performance metrics”.
Goodhart’s law
- Charles Goodhart, “Problems of Monetary Management: The U.K. Experience”, Papers in Monetary Economics, vol. 1, Reserve Bank of Australia, 1975.
- Marilyn Strathern, “‘Improving ratings’: audit in the British University system”, European Review 5(3), 1997.